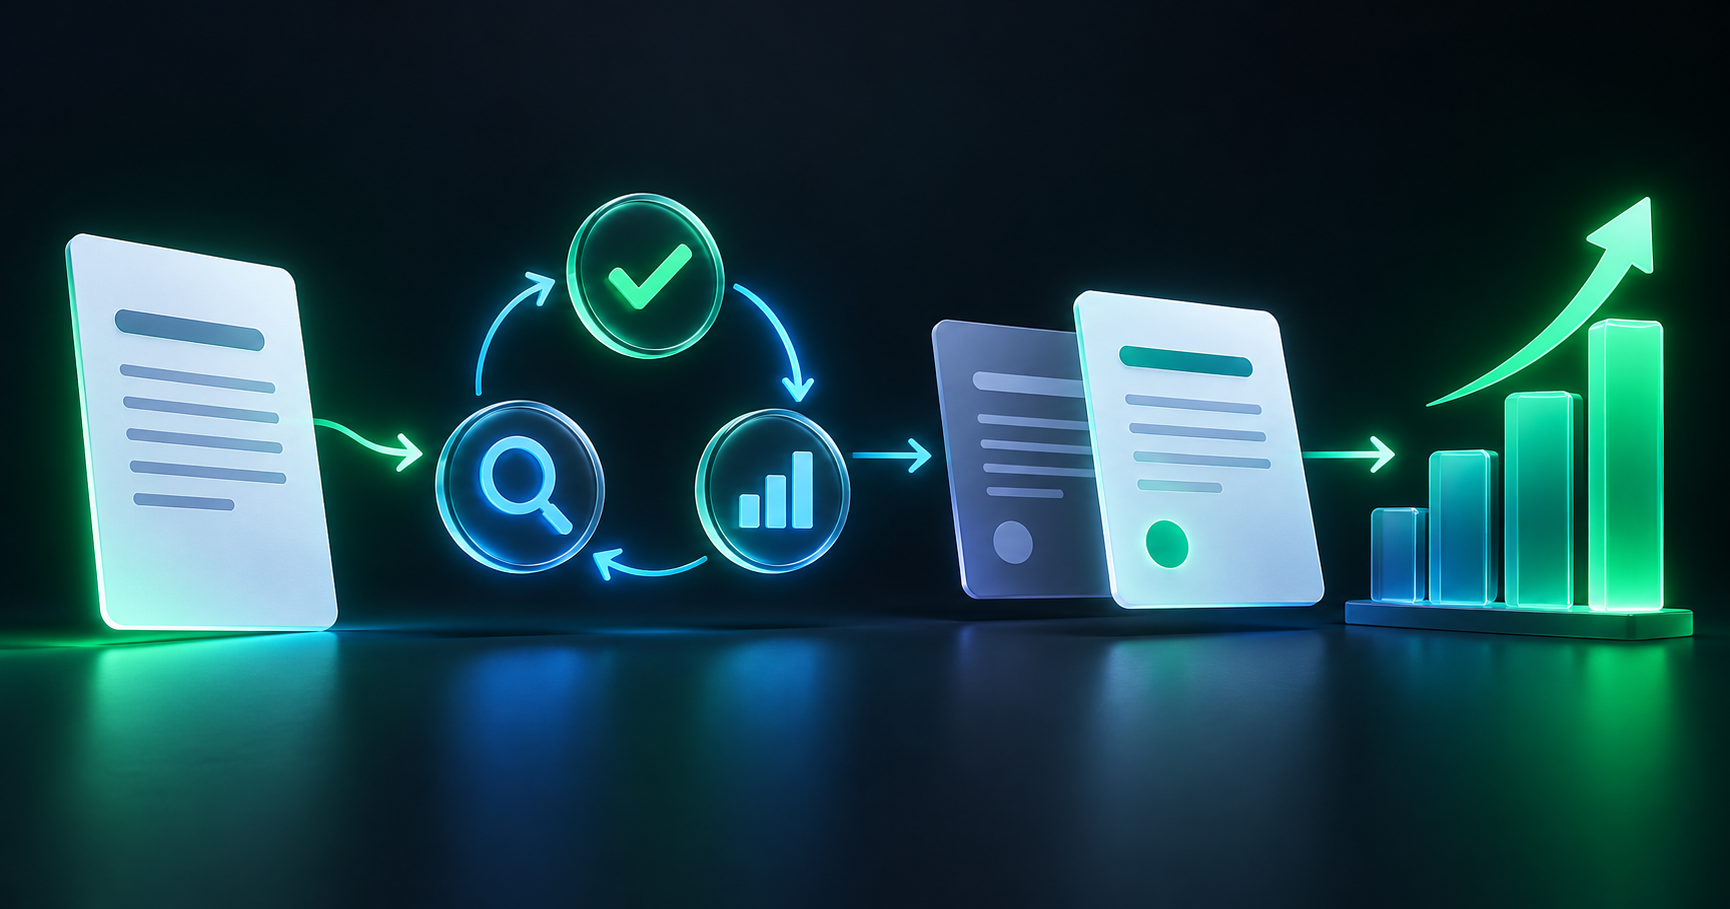
“Make the prompt better” is not a test plan. Without a definition of success, it is easy to make an output sound nicer while making it less accurate, less consistent, or harder to review. A lightweight evaluation loop gives prompt work the same discipline as any other product improvement.
Define the job and the failure modes
Start with the user’s job. What decision or next action should the output support? Translate that into observable checks: factual accuracy, required sections, tone, length, formatting, or safe handling of uncertainty. Also write down what must never happen, such as invented citations, exposed private data, or a confident answer when the source is silent.
Create a small representative test set
A useful set usually has a normal case, a short or incomplete case, a difficult edge case, and a case that should be refused or escalated. Keep the inputs stable while you compare prompt versions. If the set only contains ideal examples, you will optimize for a demo instead of the real workflow.
Change one variable at a time
Record the prompt version, model, relevant settings, input, and evaluation result. Change one instruction or one output constraint, then run the same set again. This makes cause and effect easier to see. It also prevents a long prompt from accumulating edits that no one can explain later.
Use both checks and human judgment
Automated checks are excellent for structure: required headings, valid JSON, word limits, or the presence of a source reference. Human review is still needed for usefulness, nuance, and whether the answer follows the intent of the task. Keep the review rubric short enough that two teammates can apply it consistently.
Improve the instruction, not just the example
When an output fails, ask which part of the contract was ambiguous. Does the prompt need a clearer input label? A counterexample? A rule for missing information? A format example? Fix the smallest instruction that addresses the failure, then rerun the full test set. An improvement is trustworthy only when it fixes the target case without quietly breaking another one.
Keep a decision log
For each published change, save what changed, why it changed, and which cases improved or regressed. A short log protects the team from cycling back to an old failure and helps new owners understand the trade-offs. PromptVar can keep the template, variables, and version context together so testing becomes part of the workflow instead of a forgotten spreadsheet.